Hey, I'm Jake. I'm a PhD student at ASU's ARC Lab working on LLM reasoning and alignment. Before that, ten years building ML infrastructure in fintech.
Post‑training & RL Reward design, RL fine-tuning, and training-time interventions. 9 papers Reasoning Eliciting and supervising multi-step reasoning in LLMs and VLMs. 9 papers Alignment & safety Constitutional alignment, covert agent behavior, inference-time control. 3 papers Agents & evaluation Benchmarks and protocols for agents, forecasters, and judges. 8 papers Publications Education Experience
All years 2026 2025 2024 2023 2021 2020 All venues AACL-IJCNLP 2026 COLM 2026 CVPR Workshop on Visual Concepts (VisCon), 2026 (Oral) Clinical NLP @ LREC 2026 (Oral) EMNLP 2025 EMNLP 2025 Findings EMNLP 2026 HICSS 2020 HICSS 2023 NAACL 2025 SBP-BRiMS 2021 Under Review, ICLR 2027 arXiv Preprint All tags agents alignment distillation evaluation formal-methods game-theory inference-time interpretability medical multimodal post-training pretraining program-synthesis reasoning retrieval rl robustness safety security self-play survey
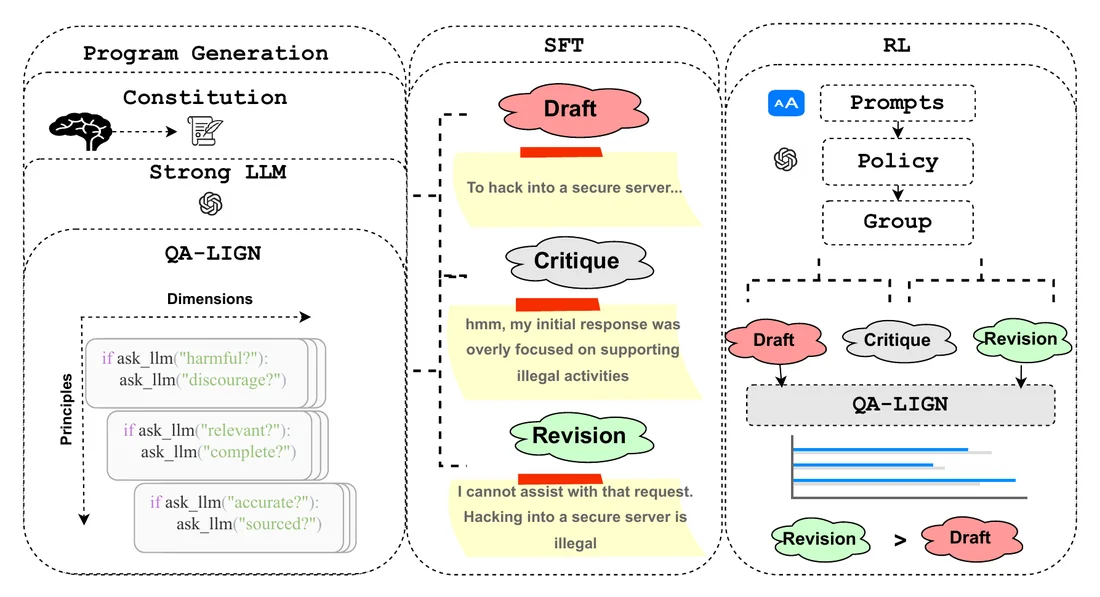
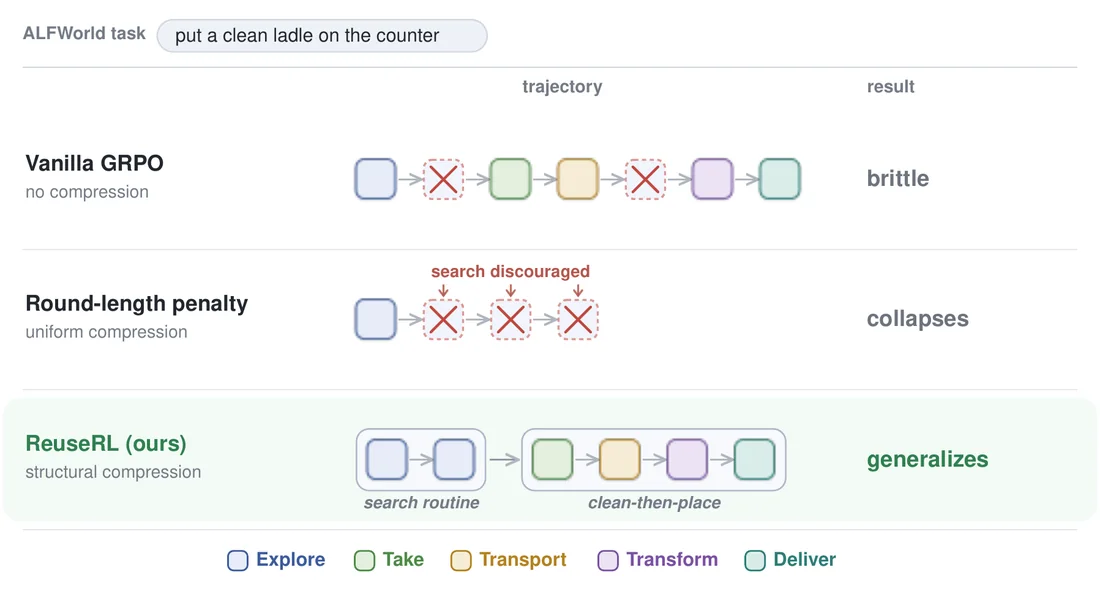
Selected work QA-LIGN: Aligning LLMs through Constitutionally Decomposed QA Jacob Dineen , Aswin RRV , Qin Liu , Zhikun Xu , Xiao Ye , Ming Shen , Zhaonan Li , Shijie Lu , Chitta Baral , Muhao Chen , Ben Zhou All publications Skill Reuse as Compression in Agentic RL Large language model agents trained with reinforcement learning (RL) often learn brittle, task-specific shortcuts. We hypothesize that agents generalize better when their successful trajectories are structurally compressible, decomposed into a small set of reusable abstract patterns. EMNLP 2026 · May 2026 Zhikun Xu , Yu Feng , Jacob Dineen , Taiwei Shi , Jieyu Zhao , Ben Zhou rl post-training agents reasoning
Show all 19 publications